Extracting Structured Data From JavaScript-Rendered Pages
Detect which pages need browser rendering before you pay the cost of running them.
This guide covers how to pull structured data out of pages that only finish loading inside a browser, and the short version is: you need a different tool for every stage, not one tool that does everything. Detection, rendering, extraction, and cleanup each come with their own bill, and paying the wrong one is how budgets disappear.
Why plain HTTP requests fail on modern JavaScript-heavy pages
A plain HTTP request to a React, Vue, Angular, or Next.js site doesn't fail the way you'd expect. The server replies, and what lands in your terminal is a nearly empty box: a skeleton like a single <div id="root"> tag plus JavaScript bundles, with the real content arriving later via AJAX or internal API calls the browser makes after the initial load. The actual prices, reviews, and listings you wanted don't exist yet. They get built after the browser downloads those bundles and runs them, which is a step a plain HTTP client never takes.
This is why the failure is so easy to miss at first. Your scraper didn't choke on messy markup or throw a parsing exception. It parsed what it was given, cleanly, and what it was given was blank. Price fields come back empty. Reviews are missing. You can spend hours debugging a scraper that is working perfectly on data that was never there.
The severity depends heavily on what kind of site you're pointing it at. On a WordPress-style site built around server-rendered HTML, a basic scraper works fine from top to bottom. On a hybrid setup like Next.js or Nuxt, where the server pre-renders some content and leaves the rest to the browser, you get partial results, some fields populated, others blank, which is arguably worse than nothing because it looks like success. On a fully client-rendered single-page app, a plain HTTP scraper comes back with nothing usable at all.
Infinite-scroll pages make the gap even wider. Only the first batch of content exists in any HTML the server sends; everything past that loads as the user (or the browser) keeps scrolling, so a static fetch only ever sees page one.
Detecting whether a page needs JavaScript rendering before committing to it
Before reaching for a headless browser, it pays to check whether you actually need one, because running JavaScript isn't free and the cost adds up fast across a large crawl. A plain HTTP request is cheap. A rendered one takes real seconds of wall-clock time and real CPU cycles, not just a longer wait. Multiplied across a crawl of thousands of pages, that gap becomes the main cost of the whole pipeline.
Mixed, real-world crawls show this pattern: most pages resolve fine with a basic HTTP request, a smaller share genuinely need headless rendering, and a thin slice need full anti-bot bypass work on top of that. Charging every page the same flat rate, as if they all needed the expensive treatment, overcharges the majority of requests that never needed rendering in the first place.
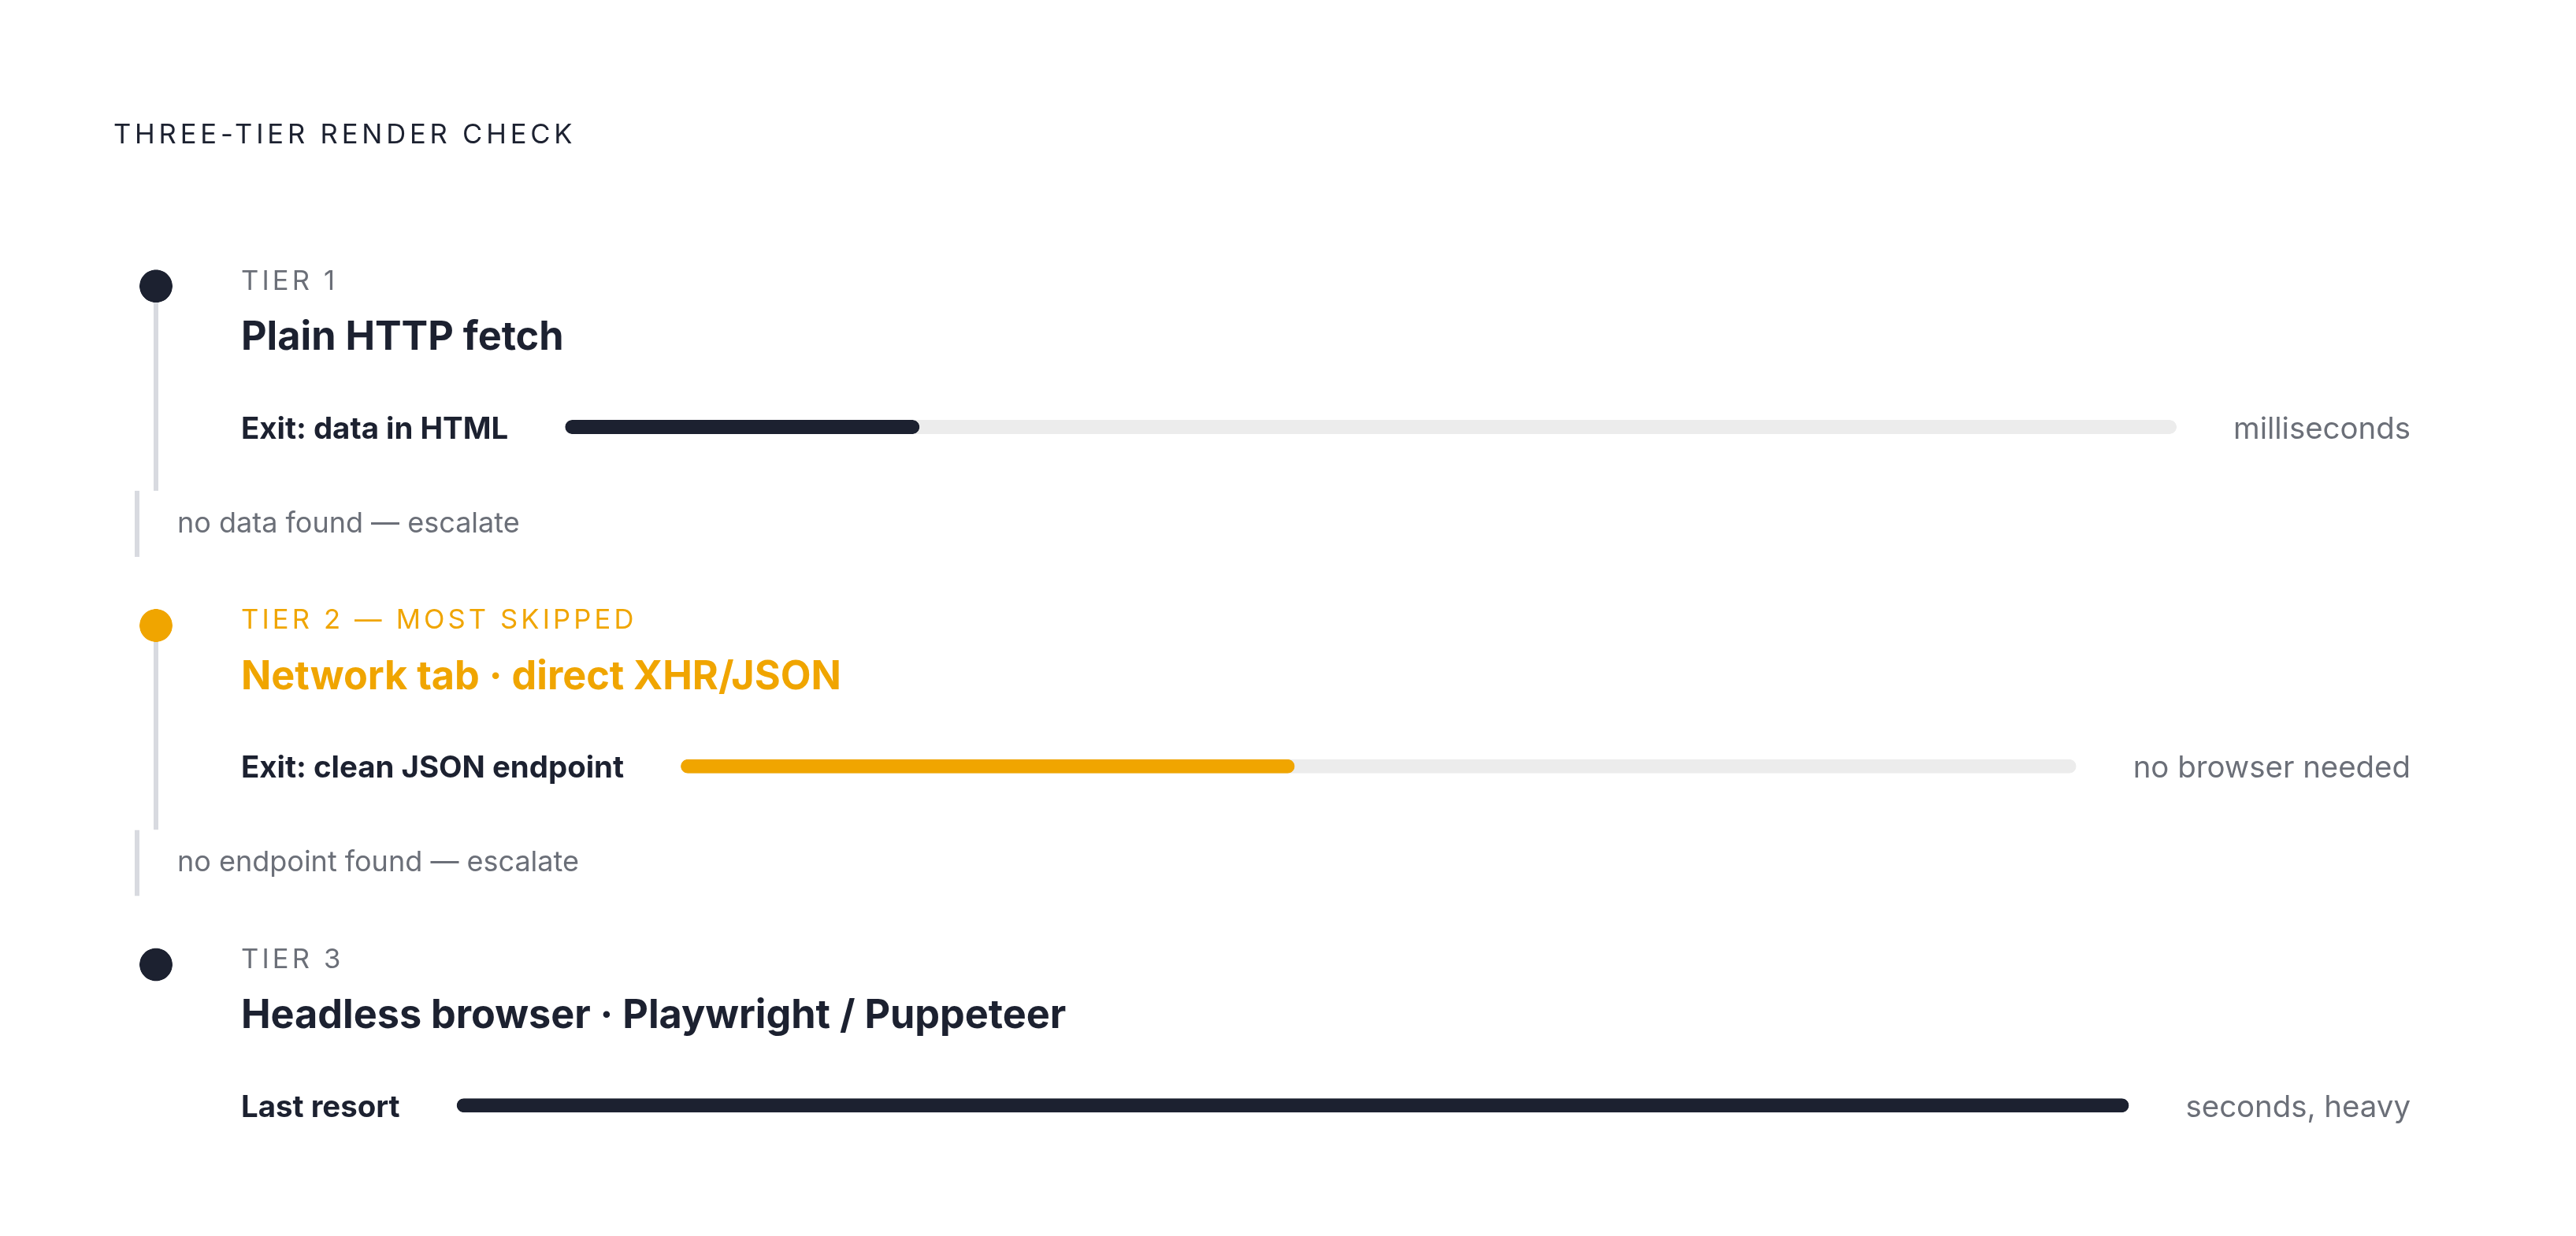
So before committing to a browser, run a simple check: fetch the page with a plain HTTP client and look for the fields you actually need in the raw response body. If the price, title, or review count is sitting right there in the text you got back, you're done. No browser required.
If it's not there, don't jump straight to Playwright. Open the page in a real browser once, watch the network tab, and look for XHR or Fetch calls that return JSON. A huge number of JavaScript-heavy sites are quietly calling their own internal API to fetch the data you want, and if you can find that endpoint, you can call it directly with a plain HTTP client, skip the browser entirely, and get data back that's already structured instead of buried in HTML. This single check is probably the most underused trick in scraping: developers go straight to headless browsers out of habit, when the site was handing them clean JSON the whole time.
Only when both checks come up empty, no data in the raw HTML and no discoverable API endpoint, does it make sense to escalate to a full headless browser.
The five rendering and extraction techniques
There's no single best technique here. The right pick depends on whether speed, reliability, or maintenance effort is the thing you can least afford to sacrifice.
Direct API interception finds the internal endpoint the page itself calls and hits it with a plain HTTP client, and it's worth trying before anything heavier. It returns clean JSON, skips HTML parsing entirely, and tends to be both the fastest and most reliable method, because you're reading from the actual data source instead of its visual wrapper. It doesn't always work. Some endpoints need auth tokens that expire on a schedule, some APIs change shape without warning, and plenty of sites simply don't expose anything discoverable. When it works, though, it eliminates the rendering step altogether, which is the whole point.
When there's no API to call, headless browser rendering is the fallback that works almost everywhere. Tools like Playwright or Puppeteer run an actual browser with no visible window, execute the page's JavaScript, and let you read the finished DOM. This handles basically any rendering technology thrown at it and supports real interaction: clicking buttons, filling forms, scrolling feeds. The price is speed and resources. Expect seconds per page instead of milliseconds, and a lot more memory and CPU burned per request than a plain HTTP call. Puppeteer specifically makes sense if the codebase is already Node.js-only, the targets are simple Chrome-only pages, and the team wants to build its own stealth layer rather than lean on a prebuilt plugin.
Once you're running a headless browser, the third technique decides how patient it is. Wait-for-element strategies pause extraction until the DOM actually has what you need, instead of guessing a fixed delay and hoping it's enough. In practice that means waiting for a specific CSS selector to show up, waiting for network traffic to go quiet, watching for a text pattern, or falling back to a flat timeout if none of those fire. Combining element detection with a sane fallback timeout tends to beat either approach alone: wait only for the selector and a slow page strands you forever; wait only on a fixed clock and a fast page wastes time, a slow one gets cut off early.
The fourth path skips running browsers yourself. Managed browser infrastructure, services like Browserbase, Cloudflare Browser Run, or Zyte API, handles the rendering and the unblocking on your behalf. Browserbase runs tens of millions of browser sessions every month, and its Developer plan bundles a set amount of browser hours, concurrent browser slots, agent runs, search calls, fetch calls, and a proxy traffic allowance before overage charges kick in. Cloudflare Browser Run spins up headless Chromium on demand across Cloudflare's network, supporting 10 requests per second for Quick Actions and up to 120 concurrent browsers. The fair objection to all of this is that managed platforms get expensive at high volume and the billing can be hard to predict. The counterargument is that if you self-host Playwright at real scale, someone on staff now has to own browser infrastructure full time, and once you price in that person's salary, the total cost often tilts back toward the managed option, though teams who've already tuned self-hosted Playwright tend to push back on vendor savings claims.
The fifth technique hands the extraction logic itself to an AI model. Instead of writing selectors, you describe in plain language what you want, and a model identifies it inside the rendered page. Because the model reads the finished, rendered content rather than raw HTML, it handles JavaScript-heavy sites fine, and when you pair it with headless rendering, you no longer have to fix broken selectors every time a layout shifts. It costs more per page than traditional parsing and runs slower because of model latency, which rules it out for anything that needs to check prices constantly or track competitors in near real time. It can also stumble when a page has several similar-looking elements sitting next to each other and the model picks the wrong one.
The extraction priority order: where to look for data in a rendered page
Once a page is actually rendered, where you look for data matters as much as how you rendered it. Some sources barely ever change; others break every time a designer gets bored. Working down from the sturdiest source to the flimsiest cuts down on maintenance dramatically.
The first place to check is JSON-LD and other embedded structured data, because it's part of the page's underlying data contract rather than something tied to how the page looks, which makes it far more stable than any DOM selector. Well-built JSON-LD is the most machine-readable signal on a typical page, and a 2026 controlled analysis found that sites with properly implemented structured data get cited in AI responses far more often than sites without it. After that comes semantic HTML: ARIA roles, data-* attributes, and microdata carry actual meaning about what an element is, rather than just how it should be styled, which makes them sturdier than ordinary class names. CSS selectors come next, and they're the default most scrapers reach for first, but they're also the most fragile: a layout tweak, an A/B test, or a seasonal redesign can snap them without warning. Last on the list is plain free-text parsing, picking meaning out of paragraph content with regex or AI, which only makes sense once everything sturdier has come up empty.
The Zyte API's automatic extraction feature is a clean example of this order in action. Instead of requesting raw HTML, a developer sets a flag like product: true, and the service hands back an object with typed fields already filled in, no selector written by hand at all. That's the priority order doing its job quietly in the background: lean on the most durable signal available, and only drop down to brittle methods when nothing sturdier exists.
Anti-bot detection of JavaScript rendering pipelines in 2026
You can render a page correctly and still not get the data off it. Modern anti-bot systems don't just watch request rates or block suspicious IPs anymore; they inspect the browser environment itself, so a perfectly rendered page can still come back blocked.
Well-protected e-commerce sites now run five detection layers before any real data gets through: TLS fingerprinting, which reads the signature of your HTTP client's handshake; JavaScript environment checks, which look for missing browser APIs, odd WebGL renderer strings, or canvas fingerprints that don't match a real browser; behavioral biometrics, which track mouse movement physics, scroll speed, and click precision; IP reputation scoring; and challenge systems like Cloudflare Turnstile. Cloudflare started blocking AI-based scraping by default in July 2025, and DataDome runs a large number of customer-specific machine learning models, so each protected site is effectively its own separate puzzle to solve.
Several tactics that used to work have stopped working. Rotating user-agents doesn't fool anyone anymore. Puppeteer-extra-stealth has gone unmaintained since early 2025 and Cloudflare catches it reliably now. Datacenter IPs and consumer VPNs get flagged fast.
What holds up in mid-2026 looks different: Camoufox, a Firefox-based tool with deep fingerprint randomization, performs well against Turnstile and against behavioral checks built to spot Chrome headless patterns. SeleniumBase's UC Mode uses a patched chromedriver binary to get around automation markers. Nodriver talks to Chrome directly through the DevTools Protocol, so it skips the higher-level automation signals that give other tools away. Curl-cffi impersonates real browser TLS fingerprints, which helps against Cloudflare- and Akamai-protected targets specifically.
The landscape shifted again with Cloudflare's Adaptive Intelligence, announced on 31 August 2026. It scores bot activity across IP addresses and time windows together, rather than judging each IP on its own request rate in isolation. That means a slow, spread-out rotation through a large pool of residential proxies can still get flagged as a single operation if the TLS fingerprint, timing pattern, and navigation behavior stay consistent across all of them. If you just spread volume across enough IPs to look like unrelated traffic, that old trick no longer holds up against this kind of correlation.
None of this is a one-time fix. A meaningful share of scraping setups need weekly patching because of DOM changes, new fingerprinting tricks, or endpoints that suddenly start throttling, and at real scale that turns into a standing engineering job rather than a side task.
Converting rendered HTML into clean, typed output for AI pipelines
Getting a fully rendered page isn't the finish line. Feeding raw HTML straight into an AI system is a poor move, since it's bloated with far more tokens than the actual content justifies, and messy, unstructured output tends to break whatever reasoning task sits downstream of it.
The token math alone makes the case. A single page of raw HTML can hand an LLM tens of thousands of tokens of input for only a small fraction of that in actual usable content, and at standard AI API pricing, that waste adds up to real budget spent on tokens that carry no information at all. Now multiply that across every page pulled into a RAG pipeline or an autonomous agent's workflow, and the wasted spend scales with the size of the crawl, not against it.
What you convert that HTML into depends on where it's headed next. A structured JSON object suits a pipeline that needs typed fields it can validate and query directly, while a different downstream use might call for clean, stripped text optimized for embedding or summarization rather than a rigid schema. The common thread across every option is the same one running through this entire piece: skip the parts of the page that don't carry information, keep the parts that do, and hand the next stage of the pipeline exactly the shape of data it asked for, nothing more.