Web Scraping APIs That Return Structured JSON for LLM Pipelines
Page retrieval—not extraction—is where most web scraping fails for AI agents.
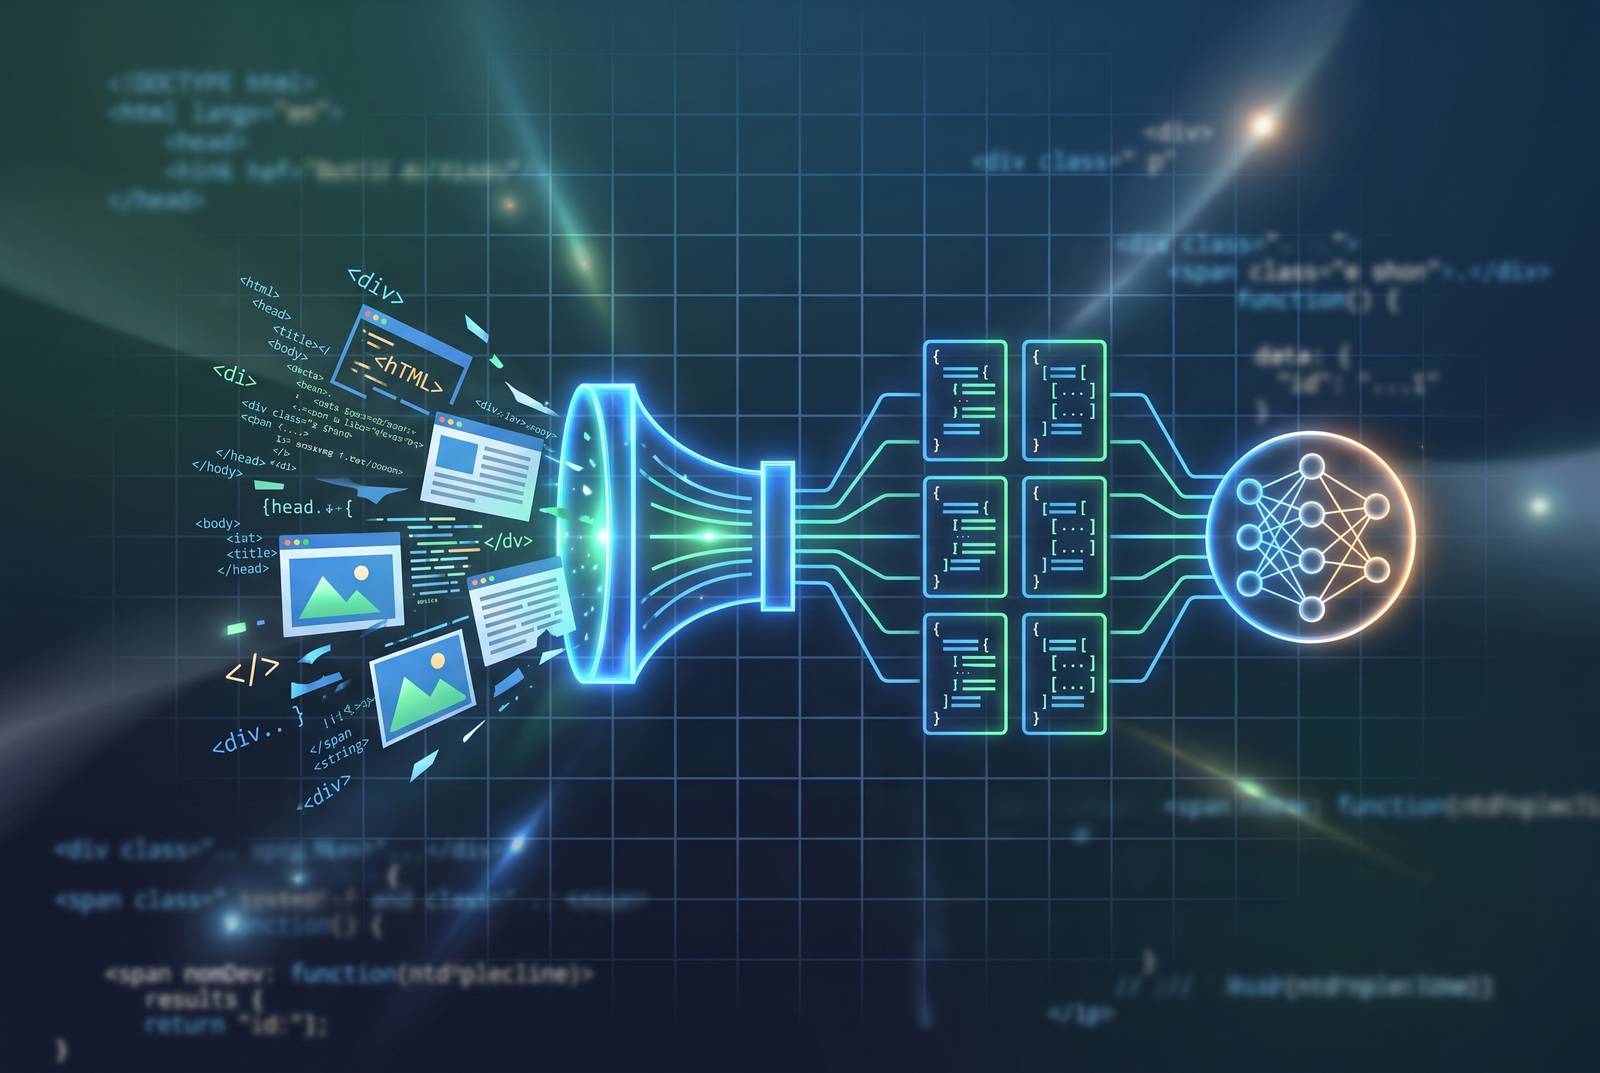
Every AI agent that fetches web pages will eventually run face-first into a login wall, a Cloudflare check, or a heavily scripted page that loads nothing but a spinner. The agent burns tokens trying to reason its way around a page it never actually saw. That's the core problem this piece is about: getting a scraping API to hand an LLM clean, structured JSON requires solving two separate problems, page retrieval and data extraction, and most failures trace back to the first one, not the second.
The NEXT-EVAL 2025 benchmark shows LLMs can hit F1 scores above 0.95 on structured web extraction, but only when the input is formatted well to begin with. That number matters because it flips the usual assumption. Developers tend to blame the model or the prompt when extraction goes sideways. Increasingly, that's the wrong place to look. The bottleneck is what's arriving at the model's doorstep in the first place, not reasoning. It's what's arriving at the model's doorstep.
The fetch layer versus the extraction layer
Two jobs, two very different skill sets. The fetch layer gets the raw page: it handles the HTTP request, renders JavaScript if needed, rotates proxies, retries failed attempts, and deals with CAPTCHAs and anti-bot walls. The extraction layer takes whatever the fetch layer hands back and turns it into something usable, Markdown, JSON, fields mapped to a schema.
Mix the two together in one black box and diagnosis becomes guesswork. Did the pipeline fail because the page never loaded, or because the parser choked on weird markup? A tool that doesn't let a developer tell the difference is a tool that turns every bug into a mystery.
The fetch layer is harder than the extraction layer, and it's getting harder every year. The WAF (web application firewall) market hit $11 billion in 2025, based on Mordor Intelligence figures cited in the research brief. Cloudflare, DataDome, Kasada, PerimeterX: these systems have gotten good enough that a homegrown scraper written over a weekend gets sniffed out and blocked within seconds on a protected domain. Add to that the fact that more than 70% of modern sites run on JavaScript frameworks like React, Next.js, or Vue, and a fetch layer that can't render JS is missing most of the content on the modern web before extraction even starts.
Vendors love to advertise "self-healing" extraction that adapts when a page's layout shifts. That's a real, useful property, but it belongs entirely to the extraction layer. It does nothing when the fetch layer gets stopped at the door by a bot check. Keep the two failure modes separate in your head, because vendors often don't separate them in their marketing.
The build-versus-buy decision comes down to who owns the fetch layer's headache. A managed API owns it for you, proxy rotation, CAPTCHA solving, all the plumbing. An open-source library hands you full control and no per-call cost, but defeating anti-bot systems becomes yours to solve.
Output format as an architectural decision, not a cosmetic one
Raw HTML is a tax that gets paid at every step downstream. The vast majority of a typical web page's raw payload is DOM structure, SVG paths, inline scripts, and boilerplate like headers and footers, none of which carries meaning. Chunk raw HTML into a vector database and most of the embedding space gets spent encoding tag soup instead of ideas.
Markdown fixes a good chunk of this for RAG pipelines. It strips out the bracket-and-tag overhead of HTML while keeping the semantic structure intact, headings, lists, paragraph breaks. That structure lets tools split content by header level instead of by arbitrary byte count. LangChain, for instance, offers splitters that chunk by header level so a vector store ends up holding whole thoughts instead of random slices of text that happen to fall at some arbitrary character length.
Structured JSON goes a step further. It preserves relationships between fields, author, publish date, canonical URL, and that metadata can ride along as payload in a vector database. Filter by a date window first, then run similarity search on what's left. That's a meaningfully different (and often more accurate) retrieval path than dumping everything into one big embedding pool and hoping cosine similarity sorts it out.
For data-dense use cases, JSON can skip embedding. Store it in a relational or NoSQL database and let the LLM generate SQL or a query language on the fly. A hybrid setup that pairs structured-query retrieval with unstructured vector search is a common approach for improving accuracy on this category of problem.
None of this matters if the data is stale. A "scrape once, embed, forget" pipeline will happily cite information that's months out of date and sound completely confident doing it. Production systems need to track when a page was scraped, where it came from, and some kind of freshness signal, then use that to re-rank or down-weight anything getting old.
The practical implication: a scraping API worth using should hand back clean Markdown, readable text, metadata, links, JSON-LD schema, section breaks by heading, and raw HTML, all as separate fields a pipeline can pick from. Different downstream steps want different formats. A tool that only gives one flavor makes that choice for you, regardless of fit.
Reading a scraping API's fetch layer before trusting its extraction claims
Before comparing extraction quality, ask four things about the fetch layer, because none of the extraction features matter if the page never loads:
- Can it get past Cloudflare, DataDome, Kasada, or PerimeterX?
- Does it actually render JavaScript, or is it limited to static HTML?
- How does it handle login walls, pagination, and multi-step flows that need more than one request?
- What's its real success rate on protected domains, not the number from a clean demo page?
Demo pages are always clean. Production pages are full of ads, cookie banners, nav menus, and popups fighting for space, and extraction accuracy on a tidy demo tells almost nothing about extraction accuracy on the mess that real websites actually are.
Watch the billing fine print too. Some vendors count a 404 or a 410 as a billable success, so a dead link still burns credits even though no content came back. Checking this before signing up for a plan based on estimated page volume matters, because a job full of broken links can quietly cost more than expected.
Scale is a fetch-layer property as much as a marketing checkbox. Concurrency limits, queueing behavior, retry logic, rate-limit handling, all of it lives in the fetch layer, and a tool that handles ten test pages fine can start dropping requests once a recurring job scales to ten thousand. Every tool discussed from here forward gets judged fetch layer first, extraction layer second, because that order reflects where things actually break.
Managed scraping APIs: fetch layer strength, extraction output, and fit for LLM pipelines
A handful of platforms have built out both layers to varying degrees. What separates them is mostly how much fetch-layer muscle backs up the extraction promises.
One class of platform bundles anti-bot bypass, JavaScript rendering, and proxy networks with geo-targeting into a single call, adjusting its bypass approach based on how hard a given target is protected. Output can come back as HTML, Markdown, JSON, plaintext, or even a screenshot, with integrations available for common orchestration frameworks. This kind of tool tends to shine specifically at the step most pipelines break on: getting the page in the first place when it's sitting behind serious protection.
Other providers lean on sheer network size, hundreds of millions of IPs, success rates in the high 90s on independent tests, uptime guarantees that stretch close to the maximum possible, plus compliance certifications like GDPR, CCPA, ISO 27001, and SOC 2. These platforms typically ship a suite: one API for structured data from a large list of pre-mapped sites, a browser API for running Puppeteer, Selenium, or Playwright on managed infrastructure, an unlocker API for the nastiest targets, and a separate product focused on search results. Pricing is at the enterprise end, which makes sense when the value proposition is "your failure rate becomes our problem."" Success-only billing can quietly turn off once custom headers or cookies get added to a request, so it pays to read that fine print closely.
A different category of tool leans into extraction built around natural-language instructions: describe the fields wanted in plain English and get structured JSON back, no selectors to write or maintain. Some ship an MCP server with a handful of callable tools, a one-command install for coding agents, and a CLI that spits out stable JSON. A few go further and offer a browser agent that can carry out natural-language, multi-step tasks on a stealth browser instance, useful for anything that needs clicking through a flow rather than a single-page grab.
There's also a smaller category built entirely around LLM-powered extraction: hand it a URL and a prompt, get Markdown or JSON back, and the extraction adapts on its own when a page's layout changes instead of breaking the way a hardcoded selector would. The tradeoff is speed and cost. LLM-based extraction runs noticeably slower and pricier per page than selector-based scraping, which matters a lot once volume climbs into the thousands of pages.
On the more traditional end sit unblocking-focused APIs built for teams that already own their parsing logic and just need reliable page retrieval. Pricing on these tends to scale by request volume and concurrency, with tiers moving from a basic plan with limited threads up through plans supporting global geotargeting and hundreds of concurrent threads. Several of these platforms also price by site difficulty, charging fractions of a cent per simple request and scaling up for harder, more heavily guarded domains. A few operate on a serverless, task-based model instead: prebuilt automation units handle scheduling, monitoring, storage, and proxy management out of the box, with an MCP layer that lets a coding agent discover available tasks, check their pricing, run them, and pull the resulting dataset back, without a developer writing custom scraping code.
The billing quirk about error responses counting as successes appears across several of these platforms, with the exact response codes that trigger a charge varying by provider. Check this on every single platform being considered, not just once.
Open-source frameworks that handle the extraction layer but require a fetch layer of their own
Open-source tools solve a different problem. They're extraction-layer software, full stop, and they generally make no claim to solving the fetch layer's hardest cases.
One well-known async Python library renders JavaScript through a browser automation tool under the hood and returns cleaned HTML, Markdown, a "fit" Markdown variant trimmed of boilerplate, structured JSON, links, media references, and metadata. Its LLM-based extraction mode lets a developer define a JSON schema, write a plain-English instruction, and pass page content through whatever LLM provider is configured, including a local model run through a tool like Ollama, and get structured output back regardless of how messy the source HTML was. It also supports chunking strategies for breaking long pages into pieces sized right for a vector database.
It can still get blocked cold by a serious anti-bot system, and it doesn't come bundled with cross-region residential proxy access. The sources reviewed are blunt about this, recommending it get paired with a managed fetch-layer service rather than deployed alone against anything seriously protected. LLM-based extraction also carries the same cost and speed tradeoff mentioned earlier, and a long enough page can trigger multiple separate LLM calls just to process one document. This tool fits best for self-hosted RAG prototypes, internal data sources, or open sites where anti-bot defense isn't a serious obstacle.
A second framework, available in both JavaScript/TypeScript and Python builds, takes a broader crawling-infrastructure approach: request queues, deduplication, routing logic, retries, concurrency control, storage, session management, proxy rotation, and support for both plain HTTP requests and full browser-based crawling. The Python build adds extraction tooling built around a model and browser-driven crawling support, and both language ecosystems support rendering of scripted pages through browser automation. For developers building their own production pipeline from scratch, this framework tends to get described as the strongest traditional option available. It still leaves defeating anti-bot systems sitting squarely with whoever's deploying it.
The pattern across both tools is the same: they're extraction-layer software wearing some fetch-layer clothing. Pair either one with a managed fetch layer for the protected sites, and the combination starts to look like a genuinely production-ready setup instead of a demo that works until it meets a real website.
Search and SERP APIs as a lightweight fetch layer for agent web context
Not every agent task needs a dedicated scraper hitting a specific URL. Sometimes the job is broader: an agent needs to know what's out there on a topic before it decides what to fetch in detail. That's where search and SERP (search engine results page) APIs earn their keep, acting as a lightweight front door to the web rather than a full-strength fetch layer.
The job here is narrower by design. Instead of rendering a heavily scripted page and bypassing a bot check, a search API returns a ranked list of results, titles, snippets, URLs, sometimes structured metadata pulled straight from the search engine's own results page. An agent can use that list to decide which two or three links are worth a real fetch call, rather than blindly hitting every URL that might be relevant.
This matters for cost and latency as much as for accuracy. A full-strength scraping API with JavaScript rendering and anti-bot bypass costs more per call and takes longer to return than a search query. Running that heavy machinery against every candidate URL an agent considers is wasteful when a lightweight search step can narrow the field first. The efficient pattern looks like this: search first, narrow down to the pages that actually matter, then bring in the heavier fetch layer only for those.
The tradeoff is depth. A SERP API gives an agent a map of the neighborhood, not a walkthrough of any one house. Once the agent has decided which page is worth pulling in full, fetching and extracting that page as described throughout this piece still has to happen, it's just been delayed until the right target's been picked. Treating a search API as a replacement for a real fetch layer, rather than a filter that sits in front of one, causes agent pipelines to reason over search snippets instead of actual page content, and that shortcut later produces a hallucination nobody can trace back to its source.