Evaluating Web Scraping APIs on Native Webhook Support Versus Bolted-On Polling Workarounds
Native webhooks beat polling for web scraping delivery speed and cost.
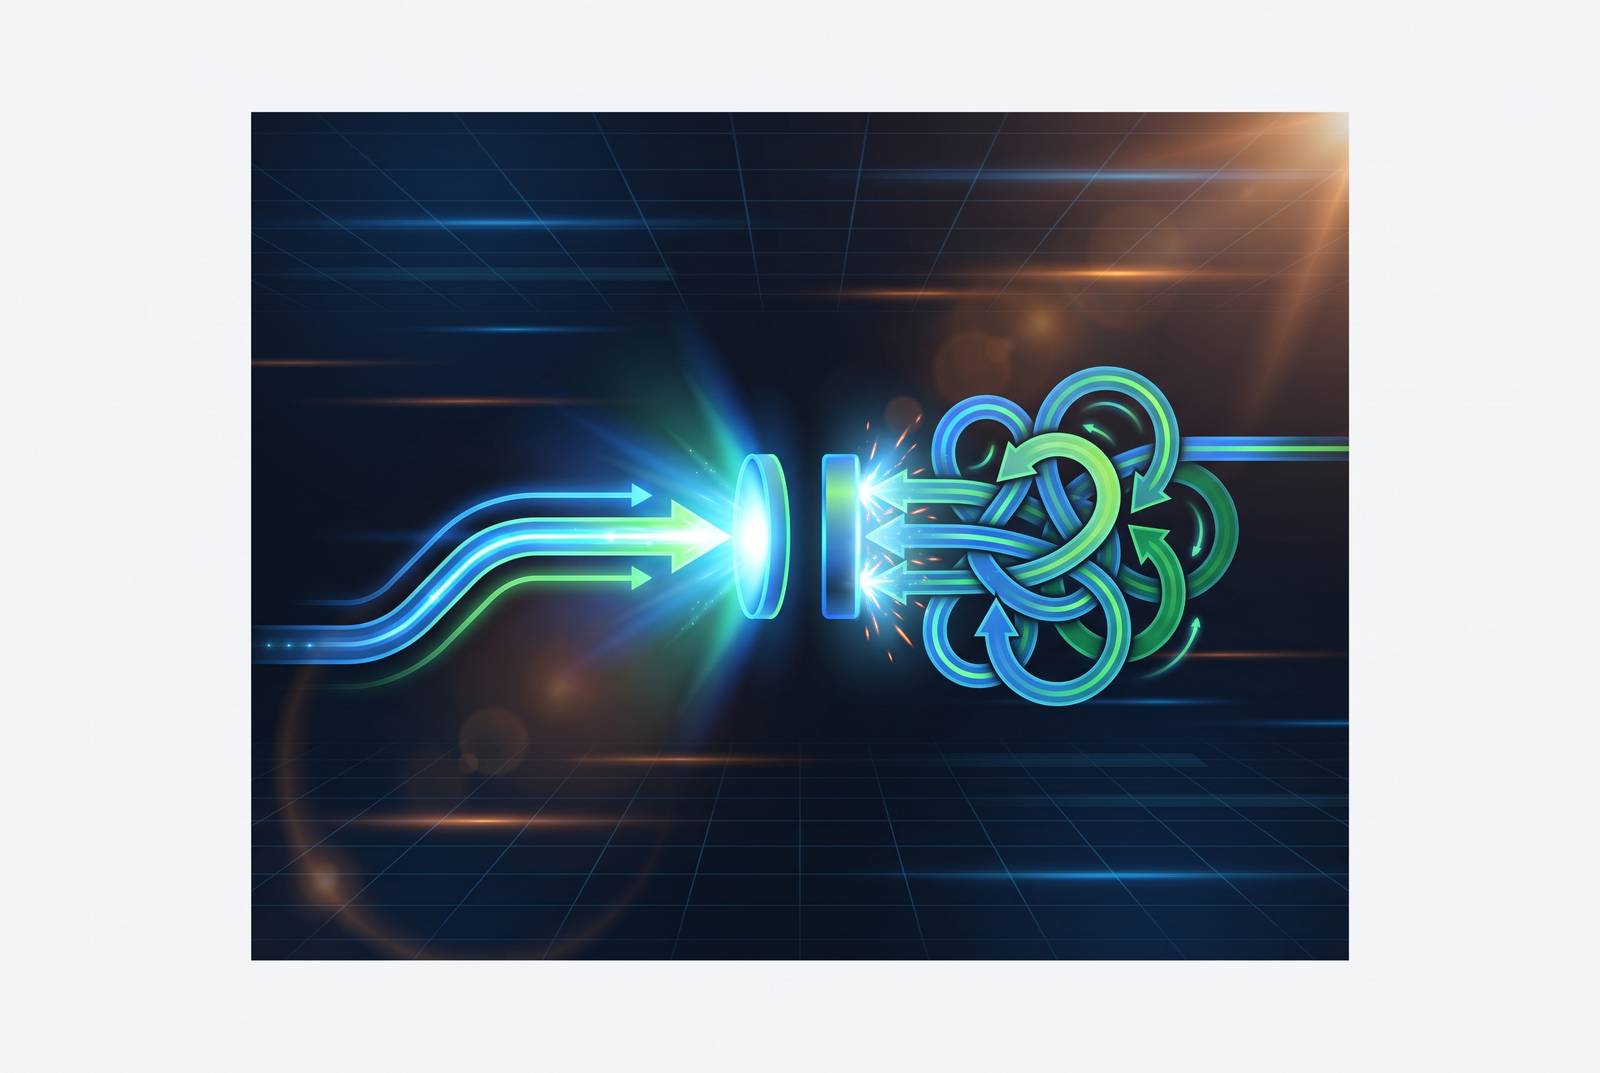
An event-driven web scraping API with webhook support should send data when a scrape completes. For AI and monitoring pipelines, native webhooks should be the primary delivery path, with polling reserved for reconciliation. Events either drive the platform or merely decorate a polling engine.
Why delivery model is an architectural decision, not a configuration choice
Either the provider delivers a completed result to your endpoint, or your system owns the loop that asks whether it is ready. That fork assigns responsibility for waiting, retries, and coordination before the first result arrives. The choice reaches into the concurrency model, cost curve, and error-handling surface of everything built above the API.
With push delivery, the provider sends an HTTP POST when data is ready, so there is no idle polling cost. Delivery often takes seconds, though how long it takes depends on the provider and conditions. With pull delivery, scheduled checks consume resources whether anything has changed or not, and their spacing sets the potential delay. Less time between checks means fresher data and more requests. Retry logic can make that arrangement more robust, but it cannot turn repeated questions into an event source.
How polling fails at the three dimensions that matter in production
Polling adds waiting after the work is done. Data can be ready just after a check and remain unseen until the next one. For fraud detection or competitive price monitoring, that gap exists before any model or downstream rule gets a chance to respond. Faster checks narrow the gap by increasing activity within the same delivery mechanism.
That trade-off becomes expensive when changes are sparse. Most checks then find no change but still use quota and compute. An agent waiting for events that rarely happen can spend nearly all its request budget asking for news that does not exist. It is like opening the fridge over and over, except the fridge charges for each visit.
The burden also spreads as sources are added. At a fixed check frequency, request volume grows with source count, and those requests need rate limiting, error handling, and backoff. Webhook receivers still need room to handle incoming events, but they do not need a new checking loop for each source they watch.
What native webhook support actually provides versus what bolted-on delivery simulates
Native webhooks make the scraping event itself trigger delivery. A completed job naturally sends its result to the configured endpoint, rather than waiting for a separate mechanism to discover completion. The event model is part of the architecture. In that design, webhooks, runs, schedules, datasets, and exports can be first-class workflow primitives, with delivery treated as a central contract.
Bolted-on delivery can look much the same from outside while working in a different way. The platform runs a polling or scheduled job internally, exposes an asynchronous status endpoint, and fires a callback when polling detects completion. Developers still face the relationship between job status and notification delivery, including ordering questions and the need to reconcile processing against the status endpoint.
Documentation provides a useful way to distinguish these designs. Webhooks presented as a top-level platform primitive signal a different integration contract from callbacks nested inside an asynchronous API path. The label alone is not a delivery guarantee. The concrete test is whether completion triggers the event directly or whether another loop must discover it first, and whether normal integration requires managing both notifications and status checks.
Idempotency remains necessary when events can arrive more than once, and ordering still needs attention where the pipeline depends on sequence. Its advantage is more specific than “webhooks are reliable.” It avoids putting a polling dependency between completed work and the event meant to announce it.
Why AI agent pipelines expose the polling gap more sharply than any other workload
An AI agent loop depends on a sequence of decisions and results. The agent decides, triggers a web fetch, receives structured data, reasons, and acts. Waiting in the fetch layer therefore holds up both a background update and the next decision. In a batch pipeline, a late result may postpone processing. In an agent loop, it can leave an action tied to conditions that have already changed.
The stale state can become an action error. Consider an outbound sequence agent that sends a follow-up to an address that has already bounced because the bounce event has not yet been ingested. The reasoning may be consistent with the available data, while the action is still wrong. Better reasoning cannot make up for an event that has not arrived.
The loop joins an LLM that decides and structures, a scraping tool that handles fetching and anti-bot work, and orchestration that chains the steps together. Clean markdown and structured JSON make fetched data usable, while fast, predictable responses keep the chain moving. These requirements belong together. Even a well-formed result can be the wrong input for a live action if it arrives too late, so delivery architecture needs as close a look as output quality. As autonomous actions become more consequential, freshness stops being a cosmetic measure of responsiveness.
Monitoring workloads and why per-fetch pricing makes the cost divergence explicit
Monitoring reverses the usual relationship between fetching and value. Competitor pricing pages, product changelogs, press release sections, and job boards may change rarely, yet a change can warrant prompt attention. Frequent checks serve that need for speed. Under per-fetch pricing, however, every unchanged result still consumes quota, so spending follows the effort to look.
A monitoring-native API uses a different billing unit. The team registers a page once and receives a webhook when a diff crosses a threshold, paying for pages watched. Cost therefore does not rise with check frequency in the same way. The provider still does the monitoring work.
That distinction also answers how to get notified automatically when a webpage changes. A monitoring-native path registers the page and a change threshold, then delivers a webhook when the threshold is crossed. A scrape-completion webhook solves a narrower problem. If the team must schedule every repeat scrape, the callback announces finished work but does not supply the monitoring workflow.
For competitive intelligence pipelines, that difference makes the delivery decision a purchasing decision as well. A per-fetch API can work well for on-demand extraction but cost more as monitoring checks become more frequent. Extra credits for diff or change detection add more charges on top. The relevant comparison is not simply the price of a successful fetch, but what the platform charges while the page remains unchanged.
MCP as a third delivery axis and what it adds to the evaluation
The Model Context Protocol adds something else to weigh alongside synchronous HTTP and webhooks. It lets an agent discover a scraping tool at runtime, read its typed parameter schema, and invoke it through a protocol the agent already speaks. That reduces the need for hand-written endpoint wrappers. For AI pipelines, tool access is therefore a distinct criterion from response format and delivery latency.
Anthropic describes MCP as an open standard for connections between data sources and AI-powered tools. The MCP specification sets out message shapes and authorization but leaves policy, quota, and audit to the host and the infrastructure around it. The process, browser, proxy network, and paid API that do the work can still run behind a closed execution layer.
A tool call may make a platform easy to reach even when its event model still depends on polling. The front door does not explain the plumbing. Evaluation needs to follow the call into execution and establish whether MCP complements native webhooks or replaces them with another path that still waits on scheduled checks.
The genuine case for polling and where hybrid architectures are the honest answer
Polling persists because its advantages are genuine and useful. A cron job that calls an API is easy to understand, has a load that is easy to predict, and makes errors straightforward to handle. It also avoids a public inbound endpoint that must be secured and authenticated. For static or batch workloads that tolerate delayed data, that can be an appropriate bargain. Polling also fits targets that change on a known schedule matching the checks, or pipelines where the team controls both sides but cannot run a public endpoint.
Webhooks bring their own obligations to the party. At-least-once delivery requires idempotency, temporal ordering may require sequencing logic, and receiver downtime can outlast the sender's retry window. Native support does not make missed events impossible. A webhook-only design that ignores recovery has traded visible checking for an unexamined failure path.
For production AI and monitoring pipelines, the practical response is a hybrid design. Events enter through a fast, authenticated webhook endpoint, are persisted before acknowledgment, and are processed asynchronously. Low-frequency polling then compares local state with the provider's API to catch what delivery missed.
An asynchronous delivery path can be useful if it supplies the required event and fields within the workload's acceptable staleness. The underlying behavior is the useful test. How often things change, what the endpoint allows, and what recovery needs decide whether that alternative is enough, whatever words its feature page uses.
How to evaluate a scraping API that sends webhook callbacks when data is ready instead of polling
For a production evaluation, begin with the required event type and fields. Establish whether the API supports them natively, then examine any webhook-equivalent asynchronous path and what it polls underneath. Set the acceptable staleness for the workload. Compare how often changes occur with how often checks would run, and establish whether the team can operate and secure an inbound endpoint. These questions define the integration needed before feature comparisons distract from it.
Next, read the documentation as an architectural map. Look for webhooks beside runs, schedules, and datasets. Ask who schedules repeat scrapes for change tracking. If that responsibility stays with the customer, a diff feature and callback do not by themselves make the service monitoring-native. Documentation structure is a signal to investigate, while the actual delivery contract determines how the system behaves.
Compare per-fetch charges with per-page monitoring charges and account for any extra credits attached to change detection. Idle periods belong in the cost assessment. An API priced for on-demand scraping may still fit the workload, but its economics should not be mistaken for those of a service built around watching pages.
Failure handling separates a convenient callback from a production-ready delivery path. Ask about the retry window, dead-letter queue behavior, signed webhooks, and reconciliation after receiver downtime. Recovery needs a defined route back to consistent state. “Re-poll the status endpoint” is inadequate as the entire delivery answer, even though periodic reconciliation is a sound supporting role. Polling can fill a gap when delivery fails or be needed for the system to work day to day.
Finally, assess whether search, scraping, crawling, monitoring, and batching share a coherent API with webhook, MCP, and SDK support, or form separate products stitched together. A unified platform can reduce the integration surface, but only if those capabilities are genuine workflow primitives. A close look at the delivery model shows whether a platform fits live AI and monitoring workloads or the earlier batch-scraping work that polling handled well.