Table and List Extraction From Web Pages
Extracted data needs semantic structure, not just text, to work with AI systems.
Pulling data off a page and pulling data a machine can actually reason with are two different jobs, and most pipelines only finish the first one, reflecting a key architectural fork separating two approaches with meaningfully different economics and trade-offs.
Surface-level extraction versus usable extraction
Getting text out of an HTML table is not hard. Any competent scraper can grab a table's cell contents with a CSS selector or an XPath query, and it will work on the first try. That part of the job has been solved for years.
Lose those relationships and the extracted text still looks fine to a person who has the original page open in another tab. They can cross-reference. They can scroll up and check the header. An AI pipeline doesn't get that luxury. It only has the extracted text, and if the extraction stripped out which number belongs to which category, or whether a list item qualifies the item above it or stands alone, the model is left guessing. Readable and usable turn out to be two separate bars, and most extraction tools are only built to clear the first one.
Why flattening structured content breaks AI pipelines specifically
A language model never actually "reads" a web page the way a person scrolling on their phone does. It processes passages, chunks, tokens, whatever the pipeline hands it, and the structure of that input shapes what the model can figure out from it. An LLM handed raw HTML straight off a page is drowning in navigation menus, footer links, cookie banners, and ad markup that carries zero information. Raw HTML runs to significantly more tokens than the same content cleaned up into Markdown, so the model is burning budget on garbage at every single call. That's money spent reading junk mail.
Stripping the noise doesn't make the problem disappear; it just relocates it. A table with its headers detached from its cells hands the model a column of bare numbers with no labels attached. The model has to guess what those numbers mean, and sometimes it guesses wrong in ways nobody downstream will catch, because the output still looks plausible. Lists have their own version of this. Flatten a nested list and drop the indentation, and a carefully structured argument (conditions here, examples there, exceptions over here) turns into a flat pile of clauses with no hierarchy left. The reader (human or model) can no longer tell what's a rule and what's just an illustration of the rule.
The measurement tools meant to catch this are shakier than they ought to be. Research benchmarking 21 PDF parsers across hundreds of tables found that the standard rule-based metrics actually reward outputs that are structurally broken, while docking points from outputs that are structurally fine but just formatted a little differently. So teams trying to grade their own extraction quality have, in some cases, been grading with a broken rubric.
How traditional extraction approaches fail to preserve structure
Selectors and XPath rules are good at one specific thing: finding a node and pulling what's there. They were never built to ask what that node means in relation to everything around it, and that gap is the whole story here.
A CSS selector that targets every td on a page will happily return the text in each cell. It has no concept of whether that row sits under a header that spans a colspan, whether it belongs to a row group, or whether a conditional subheading changes how that cell should be read. XPath does a bit better, since it can actually walk the DOM tree, but the DOM tree and the table's logical structure are not the same thing. Merged cells, header rows that span multiple columns, tables nested inside other tables (yes, that happens, and yes, it's as annoying as it sounds) all create a gap between what the code sees and what a human reader infers just by glancing at the layout.
Lists show the same gap in a smaller frame. An li selector grabs the text of each list item but throws away the nesting depth, the parent list it belonged to, and whether that list was ordered (where sequence and rank matter) or unordered (where the items are just equivalent options). None of that is a knock on CSS selectors or XPath as tools. They answer the question "where is this text," accurately and fast. They were just never built to answer "what does this text mean here," and that second question is the one AI pipelines actually need answered.
There's also a maintenance cost nobody budgets for. Traditional scrapers built on fixed selectors break easily the moment a site redesigns its layout, while AI-powered approaches tend to adapt on their own, though even those sometimes need a nudge after a major redesign. Keeping selector-based extraction running at scale means someone is on call every time a target site ships a frontend update.
What semantic reconstruction requires from an extraction system
Semantic reconstruction means recovering, on purpose, everything a human reader infers for free from layout and typography, and writing it into the output explicitly instead of leaving it implied.
For tables, that means getting several things right at once. Every data cell needs to land under its correct column header, even when that header spans multiple columns. Row-group structure needs to survive when a table uses row headers or grouped sections. Merged cells need to be flagged or resolved so whatever reads the output downstream knows which cells share one value and which are genuinely separate. And the table's caption, or the heading sitting just above it on the page, needs to travel with the extracted data, so the system knows what the table is actually about without needing the whole page reloaded for context.
Lists need a parallel set of guarantees. Nesting depth has to survive extraction so parent-child relationships stay intact. The system needs to record whether the list was ordered (sequence carries meaning) or unordered (the items are equivalent, order is incidental). The sentence or heading that introduces the list tells a reader what's actually being enumerated, and it needs to come along with it, so each item can still be read in context rather than as an orphaned fragment.
Output format isn't a cosmetic choice here, it's load-bearing. Clean Markdown preserves most of these relationships in a shape an LLM can parse directly. Structured JSON makes the same relationships explicit for pipeline code further downstream. Flat text loses nearly all of it. Agentic Document Processing, which blends multimodal models, layout awareness, and semantic reconstruction, is the current approach built around actually meeting this specification, inferring how a table works rather than flattening it into one long sequential string. The next section looks at how systems built this way actually go about it, and where they still have to make trade-offs.
How AI-native extraction approaches the reconstruction problem
LLM-based extraction throws out the fixed-rule playbook and replaces it with a model that reads the DOM the way a person skims a document: a bolded row probably means "this is a header," an indented item is probably subordinate to the line above it, and a number sitting in a cell only means something once it's tied to its column label. Transformer-based models have gotten noticeably better at parsing complex table structures and handling the kind of layered context tables often carry, which has made extraction from semi-structured HTML meaningfully more accurate and more efficient than it used to be.
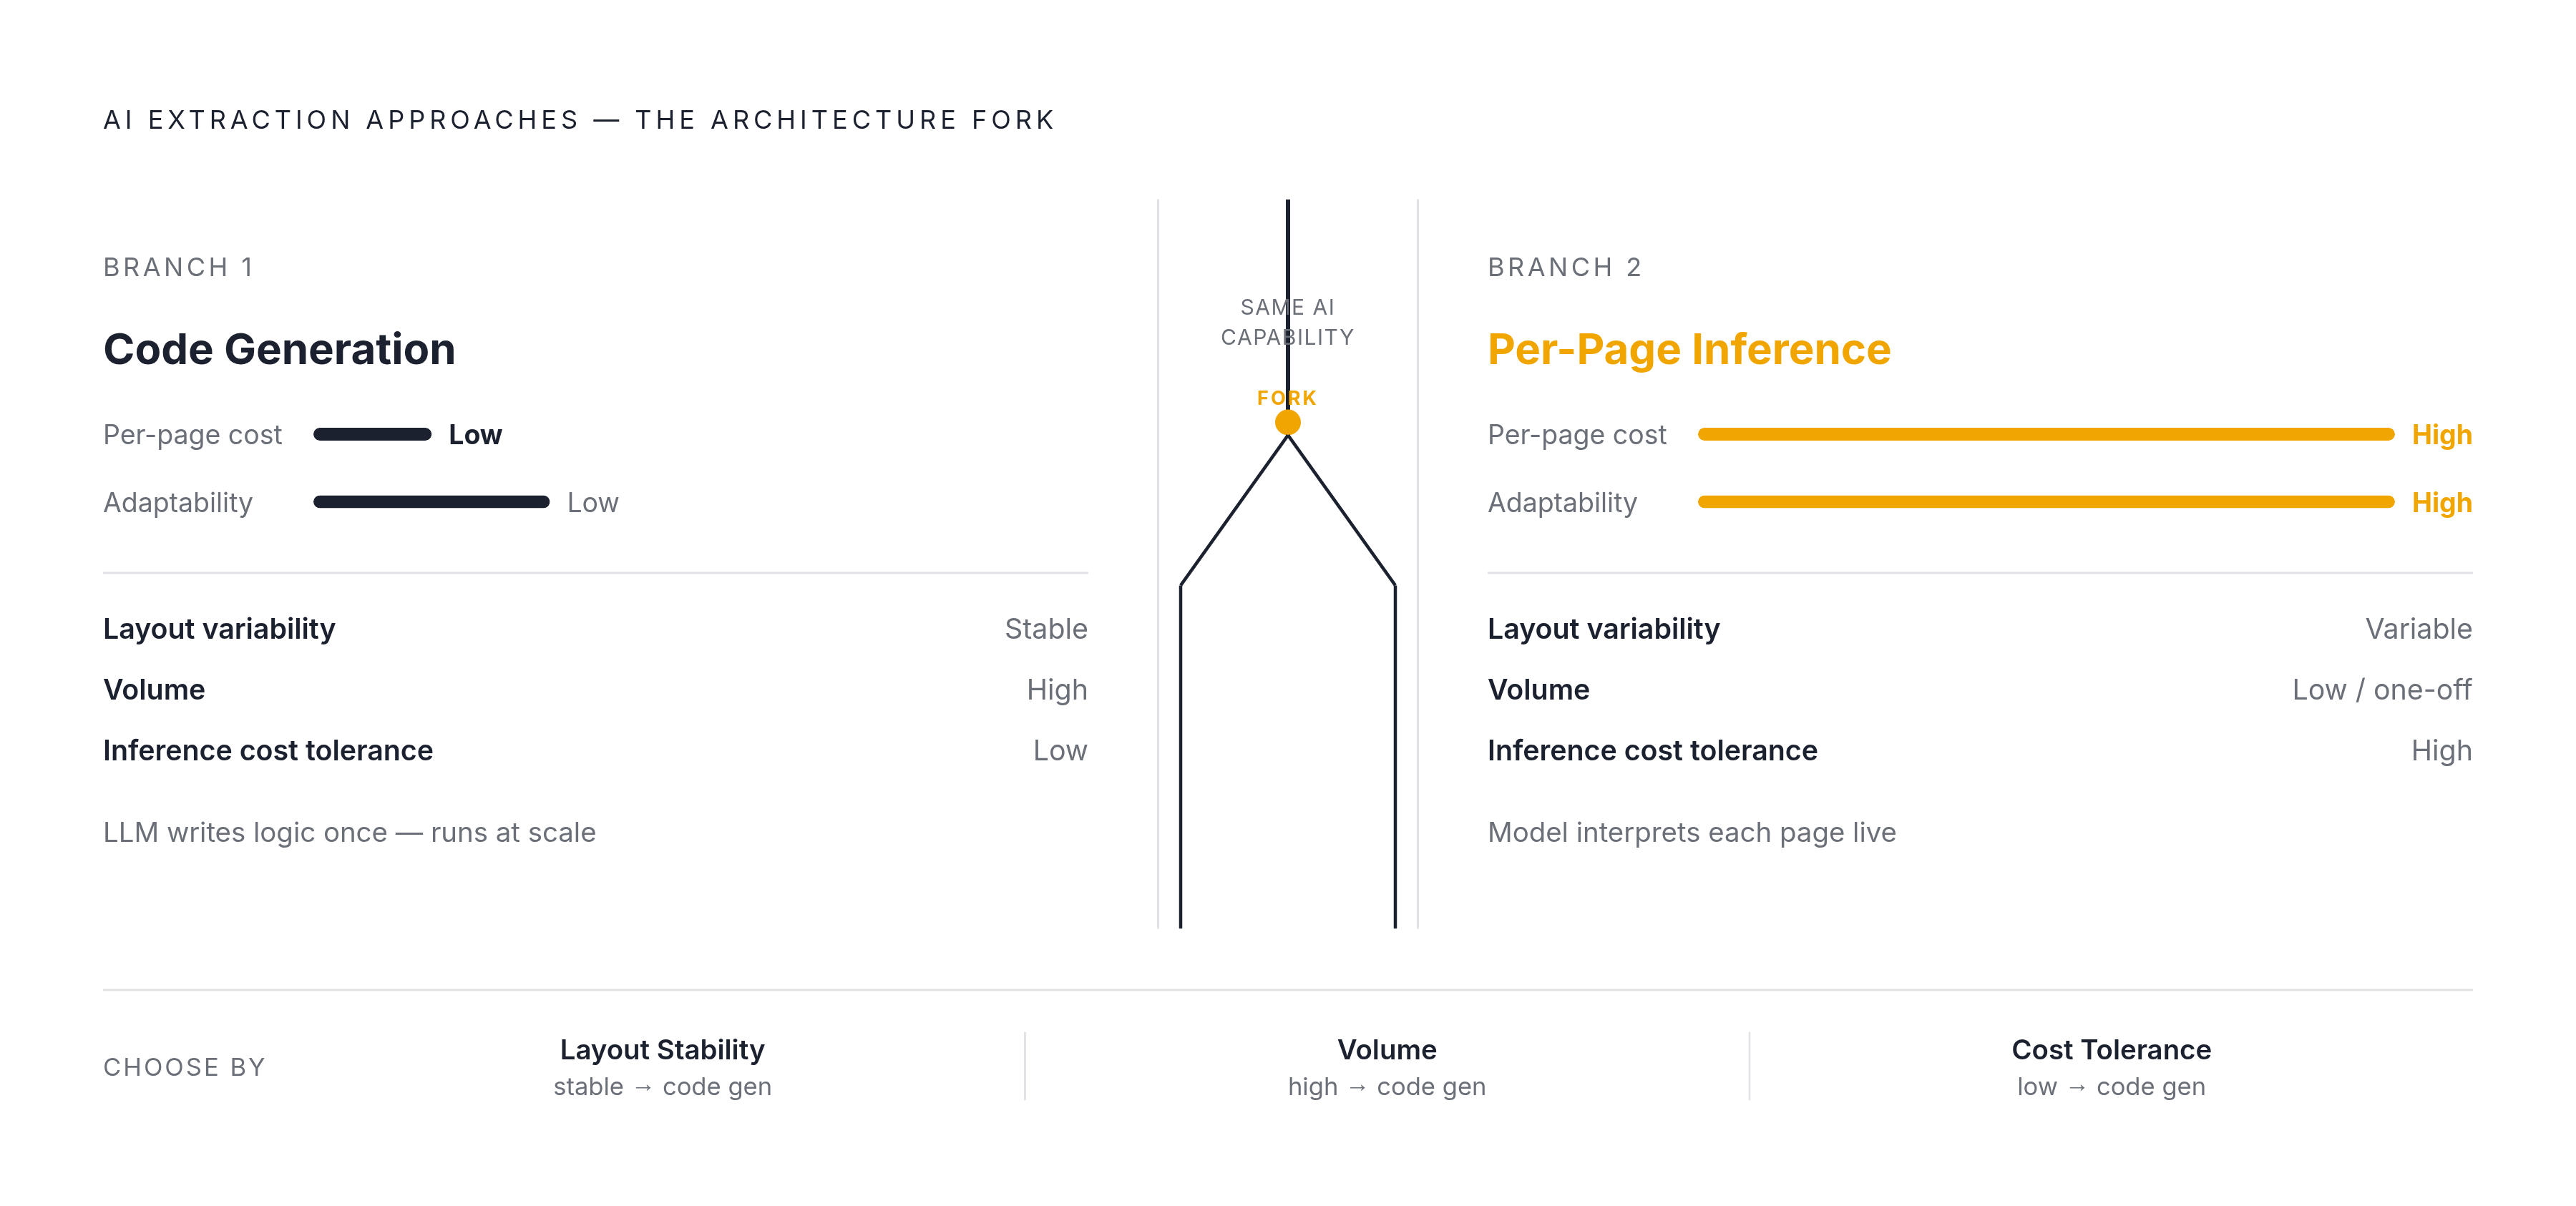
Anyone building one of these pipelines faces an architectural fork with two branches, each carrying meaningfully different economics.
One path is code generation: an LLM looks at a page's HTML structure once, writes extraction logic (selectors, rules, a script) based on what it sees, and then that logic runs on its own at scale with no further inference cost per page. This works well when the source has a stable layout and the volume is high. It's fast, it's auditable, and once it's written, it's cheap to run millions of times.
The other path is per-page inference: the model looks at and interprets every single page on its own, live, which handles layout quirks and edge cases that a one-time generated script would simply miss. The trade-off is that every page costs inference time and inference money. This path fits variable layouts, one-off jobs, or early-stage prototyping where setup speed outweighs cost per page, keeping total spend down when volume is low.
Neither branch is the correct answer in general. The right one depends on how much the layout varies, how large the volume is, and how much inference cost the pipeline can absorb per page. Self-healing extraction is a refinement of the code-generation branch: when a target site changes its layout, the system notices the extraction logic has started failing and regenerates new logic automatically, cutting down the downtime that otherwise makes selector-based extraction expensive to babysit at scale.
Not every AI-native tool reconstructs structure equally well, either. Benchmarking across 21 contemporary PDF parsers turned up real performance gaps between them, visible in whether the model reading the final output gets the right answer. Measuring that fidelity used to be the hard part, since string-matching metrics couldn't tell a genuinely broken table from one that was just formatted a little differently. An LLM-as-a-judge evaluation framework has since shown substantially better correlation with human judgment than older rule-based metrics like TEDS. Teams can now check reconstruction fidelity directly instead of settling for character overlap as a proxy.
When Each Approach Is the Right Call
AI extraction is often pitched as the thing that's replacing scraping outright, and that pitch is accurate for one regime and flatly wrong for another. It holds up for variable-layout, semantics-heavy workloads. It does not hold up for high-volume extraction from stable sources, and treating those as the same problem inflates costs that appear later as a surprise invoice.
Traditional selectors cost a fraction of what per-page LLM inference costs, and they run faster. For a pipeline pulling data from millions of pages that all share a stable, predictable structure, deterministic extraction still wins on cost and speed, full stop on the math.
The case for AI-native reconstruction gets stronger as layout variability goes up, the ongoing cost of patching broken selectors goes up, and the thing consuming the output downstream is an LLM that needs semantically coherent input rather than raw scraped text. If the target is millions of records that all look alike, write the extraction code once and let it run deterministically forever.
Before comparing tools or vendors at all, it helps to nail down the basics first: which sources need covering, which fields are actually required, how often the data needs refreshing, and where it needs to land once it's extracted.
Designing extraction pipelines with structure fidelity as the explicit goal
Structure fidelity needs to be a named line item in a pipeline's requirements. Teams that never test for it explicitly won't find out it's missing until a model downstream starts handing back wrong answers with total confidence.
A pipeline actually built around structure fidelity does a few concrete things. It picks an output format based on what's consuming it downstream: Markdown when an LLM reads it directly, JSON when it's headed into a database, structured excerpts when it feeds a retrieval-augmented generation system, never raw HTML passed through at any stage. It defines a schema before a single line of extraction logic gets written, mapping every required field to a source and a fallback, and enforcing a strict "none found" rule rather than letting the extractor invent a plausible-looking value when it comes up empty.
It tests extraction quality semantically, using an LLM-as-a-judge setup or a human spot-check against known-correct ground truth, instead of leaning on string-match metrics that reward structure that merely looks preserved while missing content errors entirely. And it watches for structural drift: when a target site changes its table layout or reshuffles a list, the pipeline flags the change or regenerates its own extraction logic before bad data ever reaches whatever's consuming it downstream.
The extracted structure's destination has shifted. MCP (Model Context Protocol) integration moves the destination away from a dashboard or a database table and toward the AI agent a developer is already working in: a hosted service watches pages on a schedule and delivers judged, structured changes straight into that agent, closing the gap between spotting a change and acting on it. The table was always there, headers and all. The job was never extraction. It was reconstruction, and that's the part the industry is only now starting to measure correctly.