Field-Level JSON Extraction From Product Pages and Articles for LLM Reasoning
Define the schema first, then validate every extracted field.
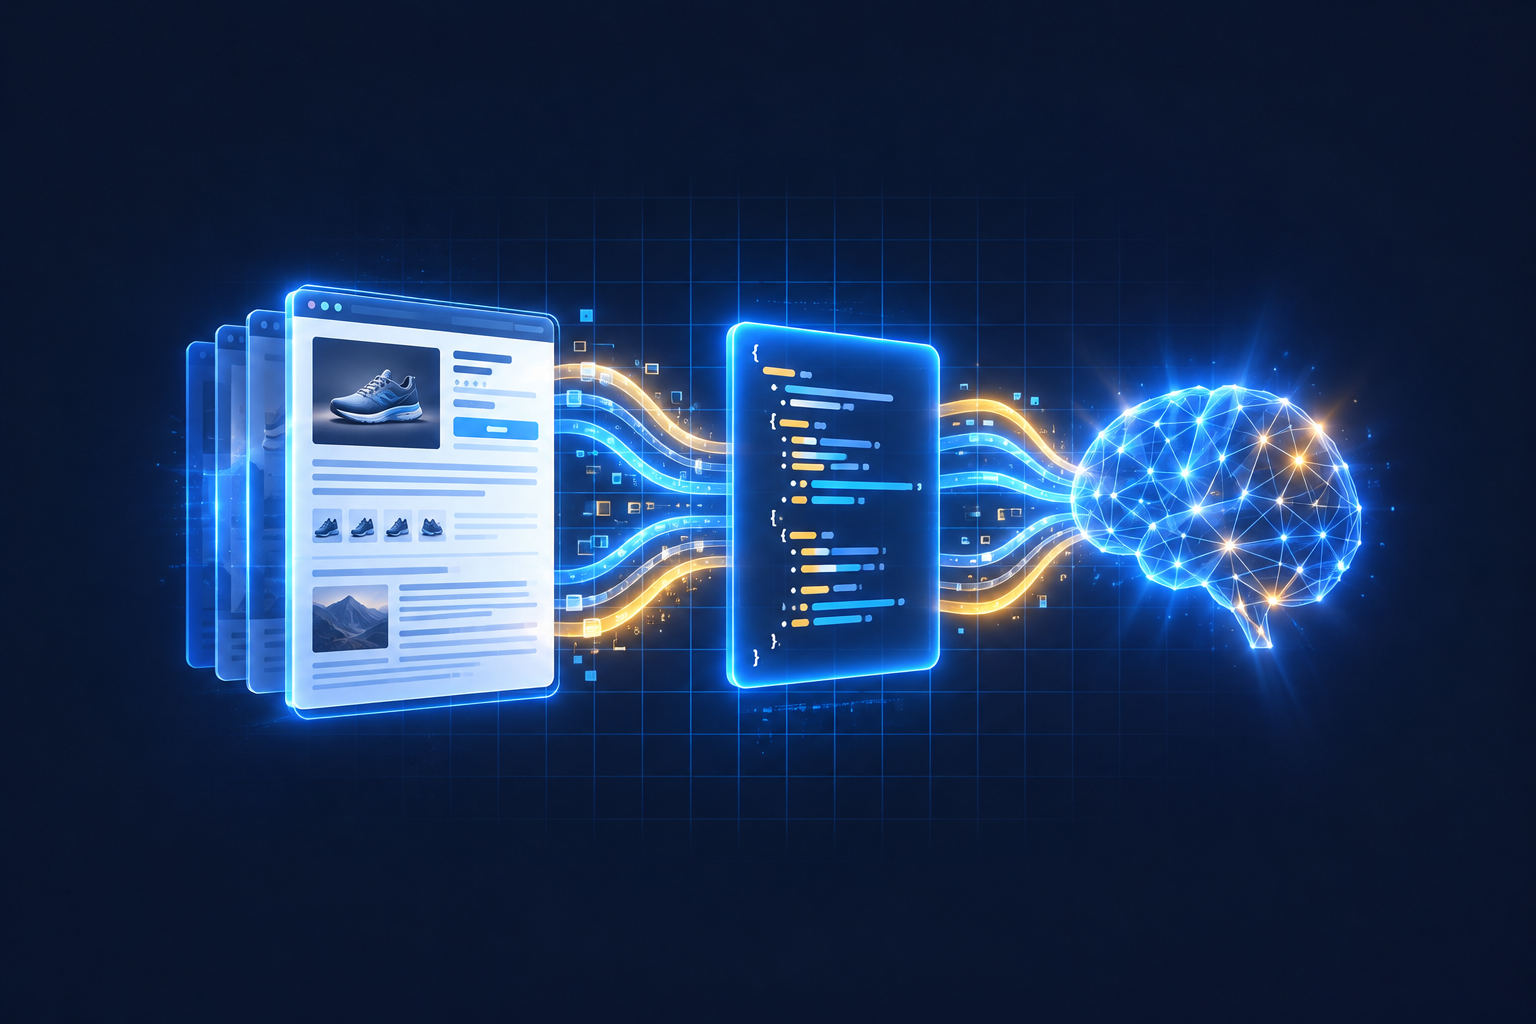
Field-level JSON extraction turns product pages and articles into typed data that an LLM can use without more cleaning. The reliable approach is to define the output schema first, then fetch, clean, extract, and validate page content against it. This makes extraction an architecture decision because downstream reasoning depends on the contract every upstream layer must satisfy.
Why field-level JSON extraction has become the entry point for LLM reasoning pipelines
A brittle selector misses a price, the pipeline accepts the missing value, and a three-day debugging spiral begins. Nothing crashed. That is the problem with silent failures in web extraction, where broken inputs can travel much further than obvious errors.
Raw HTML adds another source of confusion because it is a delivery format for browsers. Wrappers, tracking scripts, inline styles, and SVG icons compete with the actual content. A product-heavy homepage can contain tens of thousands of HTML tokens while its extracted JSON takes a few hundred. Price comparisons and availability checks later in the pipeline get that same noise unless extraction pulls the facts out of their packaging.
What schema-first means and why defining output structure before writing a prompt changes what you build
Schema-first means defining field names, types, required values, optional values, and nested objects before writing a prompt or selector. The schema sets the assignment. Instead of asking a model to describe a product, the pipeline asks it to fill a specific contract that later code can validate.
In Python, Pydantic serves both as the definition of that contract and the validator for returned data. A product model can define name and description as strings, price as a float, currency as an ISO 4217 string, and in_stock as a boolean. Optional fields include original_price, rating, review_count, and a nested seller object using SellerInfo. Field descriptions help with extraction by explaining what each value means, and Zod does the same job in TypeScript.
Types alone do not establish correctness, however. A float accepts -9.99 just as readily as a sensible price, so the contract also needs a rule enforcing price > 0. Missing information needs an explicit policy too. Allowing null for an optional rating is different from silently accepting a missing required price.
How do you get web page content into a format an LLM can use without cleaning it first?
The cleaning still has to happen, but it belongs upstream of the reasoning model. It should leave text with no tags, scripts, or boilerplate, keep the content hierarchy, and use the same format across pages. Markdown works at this step because it keeps headings, lists, and tables without HTML’s bulk. The model needs the product content.
This preparation is the biggest token-cost lever in the pipeline, before model selection enters the discussion. Even a rough pass that removes scripts, styles, headers, footers, and sidebars reduces what the model must process. A self-managed stack may combine HTTP fetching, Playwright or Selenium for rendering, and BeautifulSoup or lxml for parsing. Each handoff adds a possible failure point.
For JavaScript-heavy pages, rendering is essential because a static request may return only an empty shell. A managed scraping API can handle rendering and the associated fetch infrastructure instead. Rate limiting and URL deduplication also belong here, although their full consequences emerge when the pipeline runs across many URLs.
Passing clean content through a schema to get typed JSON — the extraction call itself
OpenAI’s structured-output pattern starts with Pydantic’s model_json_schema() method, which converts the model definition into JSON Schema. The API call receives that schema through response_format with the type set to json_schema, together with the cleaned page content. The returned JSON string then passes through model_validate_json(). This connects the requested shape to the validation contract.
The prompt can stay short and specific. It asks for structured extraction, valid JSON matching the schema, and null for fields that cannot be determined where the contract permits null. It also tells the model not to invent values. Sending only the most content-dense part of the cleaned page reduces cost, although truncation must not remove the fields being requested.
OpenAI, Claude, and Gemini support structured output, but that alone is not enough to choose a model. The useful evaluation criteria are extraction accuracy, schema adherence, context window, cost, and speed. A smaller context window may call for chunking, which adds work and can split up fields that belong together. Local inference is also relevant where data-residency requirements or high volumes shape the decision.
Validating output and handling failures so silent errors don't reach downstream reasoning
The most dangerous output is plausible but wrong. A model can return a competitor’s price from elsewhere on the page, make up a description, or flip an availability boolean and still return valid JSON. Schema validation catches structural errors. A well-dressed error is still an error.
Production validation therefore combines type checks, semantic rules, and corrective retries. Type checks catch required fields that are missing, wrong types, and nulls that are not allowed, while semantic rules catch values such as a price at or below zero. When Pydantic raises ValidationError, the next prompt includes that specific error. If the price violates price > 0, the correction identifies that failed constraint so the model knows what to revisit.
Few-shot examples that return null for missing fields help keep the model from making up values. Results that still fail sanity checks belong in manual review, including a price that resembles a date or a name that is a URL. Retry counts per URL, schema failure rates per domain, and correction-prompt success rates reveal whether this layer is improving output or merely staying busy.
Tiered fallback strategy — when to use LLM extraction and when structured markup makes it unnecessary
Schema-first does not mean sending every page to an LLM. JSON-LD may already have the fields being requested, so extraction can work without a model call. The schema remains the contract regardless of which method supplies the values.
A tiered pipeline tries cheaper extraction methods first, then uses the model for pages that need it to work out what the content means. For high-volume work on one domain, another pattern reverses the model’s role. The LLM generates CSS selectors from a sample page, and traditional scraping then applies those selectors across pages sharing the same DOM structure.
That approach pays the reasoning cost once rather than on every page, but its usefulness depends on domain consistency. Across thousands of unrelated sites, selector maintenance can make full LLM extraction the lower total-cost option when engineering time is included. Semantic extraction is more resilient to redesigns because it locates content by meaning. It still depends on receiving the relevant content.
Pipeline architecture for processing URLs at scale — fetch queue, deduplication, extraction, checkpointing
At scale, the fetch queue must respect the speed of the extraction layer. Bounded async queues apply backpressure when consumers fall behind, slowing producers and keeping memory use in check. Speed without bounds adds to the pile of work still to be done.
Deduplication keeps the same page from showing up in that pile again and again. URL canonicalization includes lowercasing the scheme and host, sorting query parameters, and stripping tracking tokens such as utm_source. Redis SETs avoid the false positives of Bloom filters, which can silently discard valid URLs. Per-domain token-bucket rate limiting controls how many requests go out, often starting with one request per second per domain.
Checkpointing protects completed work when a crawl stops midway. SQLite, Redis, or flat JSON can hold checkpoints for different scales, allowing a restart without paying again for every processed URL. Fetch infrastructure also needs to account for blocking at volume, including per-request proxy rotation. Residential proxies can become the largest infrastructure cost at high page volumes, so token pricing is not the whole budget.
Applying the pipeline to product pages — extracting price, availability, rating, and seller fields reliably
A current price may appear near an original price, ratings near review counts, and seller details near other offers. The model must preserve those associations. Finding a number is easier than identifying whose number it is.
The Amazon example in the notes shows what the output should look like even when the source HTML is messy. It represents the title as the full product name, price as a normalized decimal string, currency as "USD", sku as the ASIN, availability as "InStock", and rating as a structured string. Those representations differ from the earlier Pydantic contract, which uses a float price and boolean in_stock. The pipeline must choose its contract deliberately rather than allow both formats to drift into the same dataset.
A visible symbol-prefixed price and a locale-formatted value can be interpreted semantically, but a value stored only in a data-price attribute must reach the extractor to be usable.
For catalog jobs, async batching dispatches extraction tasks concurrently and collects results as they finish. Each record goes through the same validation gate before it is saved. Using the same format helps with competitive pricing, inventory monitoring, recommendation data, and market analytics, so each downstream consumer can use the data without untangling how the retailer formats it.
Applying the pipeline to articles — extracting structured fields from editorial content for LLM consumption
Articles use the same mechanics but need a different contract. Their core fields are headline, author, publish date, body text, and summary, with canonical URL providing useful metadata. Markdown preserves heading levels, lists, and blockquotes while removing navigation and related-article widgets. Editorial content needs its own boundaries respected.
For RAG, the schema should include body_text for the full cleaned article, summary for the generated summary, and published_at as an ISO 8601 datetime. The body gives retrieval its content, and the date shows when it was published, which may be hard to tell from the prose alone. Missing dates, truncated summaries, and boilerplate mixed into the body can degrade retrieval and generation. Fine-tuning datasets also need a consistent format across records, rather than an accidental mixture of Markdown and plain text.
What breaks the pipeline in production — JavaScript rendering, bot detection, and site structure changes
A JavaScript rendering failure can deliver an empty page shell to an otherwise correct extractor. If the schema permits nulls, the model may return an all-null object that looks like a successful job. Browser rendering addresses the missing content.
Bot detection produces a different substitution. Cloudflare, Akamai, and DataDome can return challenges instead of the requested content, leaving the model to process the wrong page. Proxy rotation, browser fingerprint management, and challenge handling belong in the fetch layer, whether self-managed or provided through a managed API. Calling extraction again will not fix a blocked fetch.
Site redesigns and A/B tests can break selectors or move fields beyond the portion of content sent to the model. LLM extraction is more resilient to location changes, but truncation can still hide the evidence. A jump in schema failures for a domain suggests that the content structure has changed, while a sudden rise in null rates can point to trouble with the fetch or rendering. Resuming from a checkpoint only helps once the fault is fixed, or the crawl comes back to the same locked door.
How the validated JSON object feeds LLM reasoning — from extracted fields to pipeline decisions
Typed price, in_stock, and rating fields support structured comparisons, price-undercut detection, and availability-gap analysis. The model can reason over those fields without first reconstructing the page. Its context has a defined shape.
A published_at field lets a pipeline filter, rank, or weight sources by recency without repeatedly interpreting inconsistent date strings. Scheduled product extraction can also compare current and previous JSON, triggering a notification, repricing action, or battlecard update when a typed field changes. The comparison is deterministic even when the source pages look different.
MCP-based agents can request extraction on demand and receive a typed object within the same reasoning loop. That interface makes web research composable without a separate preparation job for every request. Schema-first architecture gives downstream agents a stable contract for comparison, retrieval, and action, while keeping the responsibility for trustworthy evidence upstream where it belongs.